Check the serving stack before you blame the model
· re: Drinking Our Own Champagne, Part 6: The Model Was Rarely the Problem (Upbound)
Check the serving stack before you replace the model.
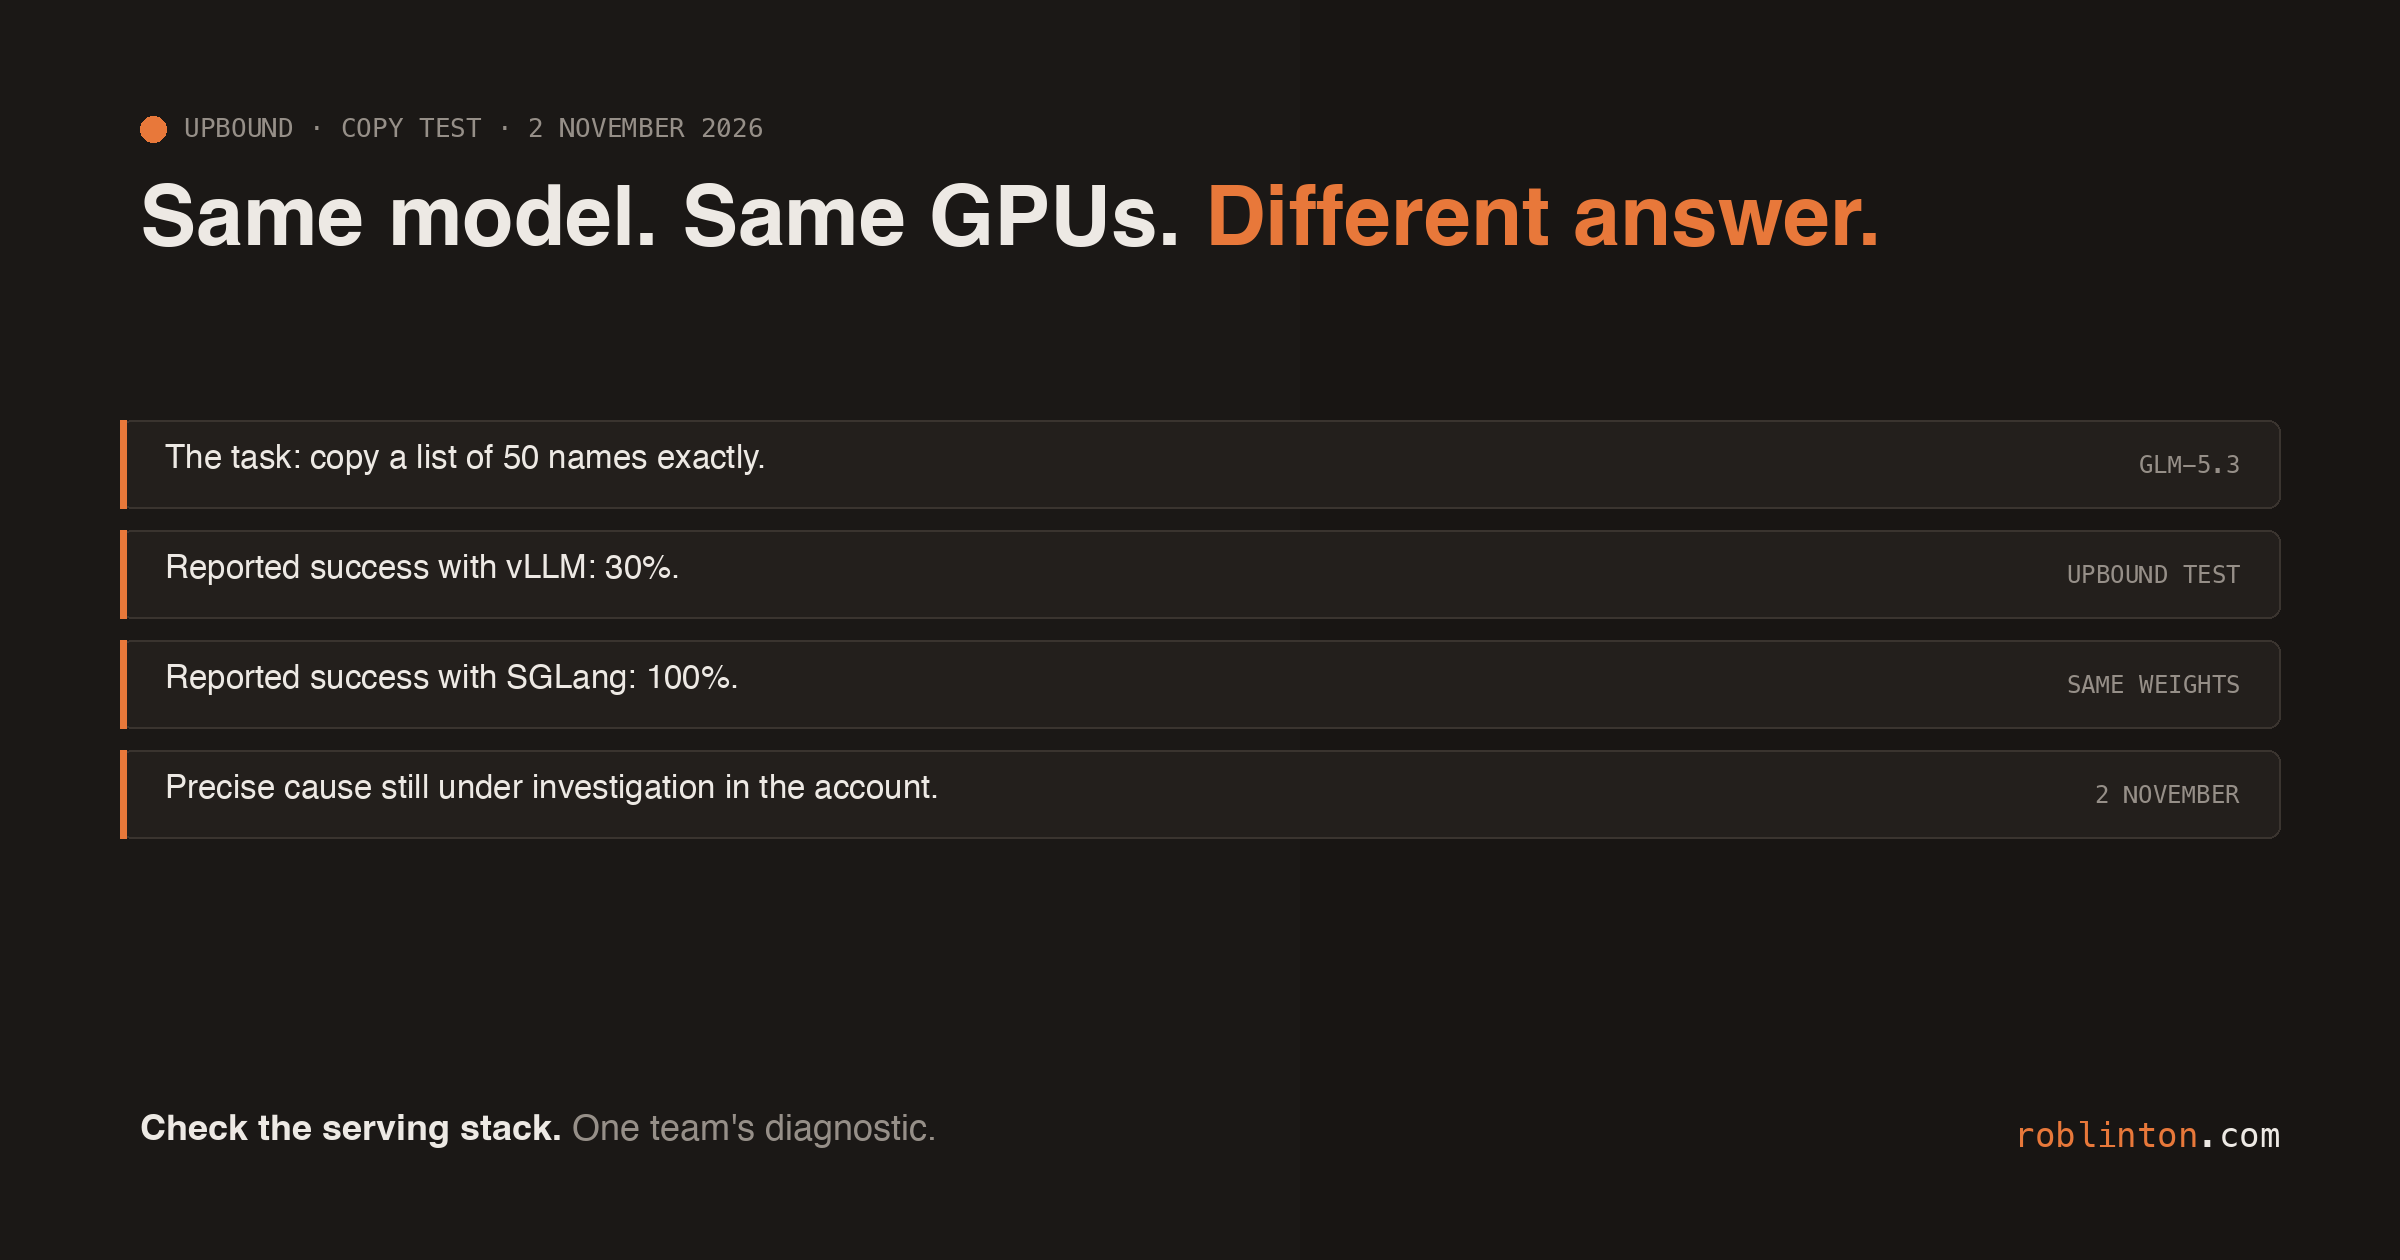
In its 2 November account of running models internally, Upbound describes a simple test: ask GLM-5.3 to copy a list of 50 names exactly. The team reports 30% success on vLLM and 100% on SGLang, using the same model weights and GPUs.
(Copying fifty names is a fairly modest job description.)
For about two weeks, broken tool calls and invented values had looked like a model problem. Upbound attributed the failures to its serving stack and said it was still investigating the precise cause with the vLLM maintainers.
This is one team’s diagnostic, not a general ranking of those engines.
My read: keep a small test with a known answer alongside the tests for your actual workload. Run it through the system your users reach, including the gateway and serving engine. A successful HTTP response tells you very little if the answer has been cut short.
Before spending another week comparing model scores, check that the software delivering the answer is delivering all of it.